From Real-WorldMotion toGeneral Skills

Rooted in 3D vision and brain-inspired science, we turn real-world motion, interaction and manipulation into data and skills machines can learn and execute — research and product run on one pipeline.

View Publications ↓
SEC / 01 · RESEARCH LINESACTIVE — 03 UNITS

Scalable Production of Human Behavior Data

Replacing studio motion capture with a video-in, data-out pipeline: from monocular to multi-shot, from body pose to finger contact and facial expression — whole-body 3D motion with semantic labels, the academic foundation of the UNIData million-hour asset.

Embodied Perception and Generalizable Manipulation

From understanding objects to grasping them: category-level detection, pose estimation and 3D reconstruction from stereo vision in a single stage, with a frozen VLM perception layer focused purely on manipulation — so robots succeed on objects and scenes they have never seen.

Data Engine and Cross-Embodiment Skill Transfer

Human demonstrations as the data source: hand-object interaction videos are physically refined and retargeted across embodiments into executable trajectories for robot arms, dexterous hands and humanoids — turning one person’s motion into a skill for every body.

SEC / 02 · PUBLICATION LEDGERVERIFIED — 06 ENTRIES

01Scalable Production of Human Behavior Data

03 PAPERS
Motion-XNeurIPS 2023
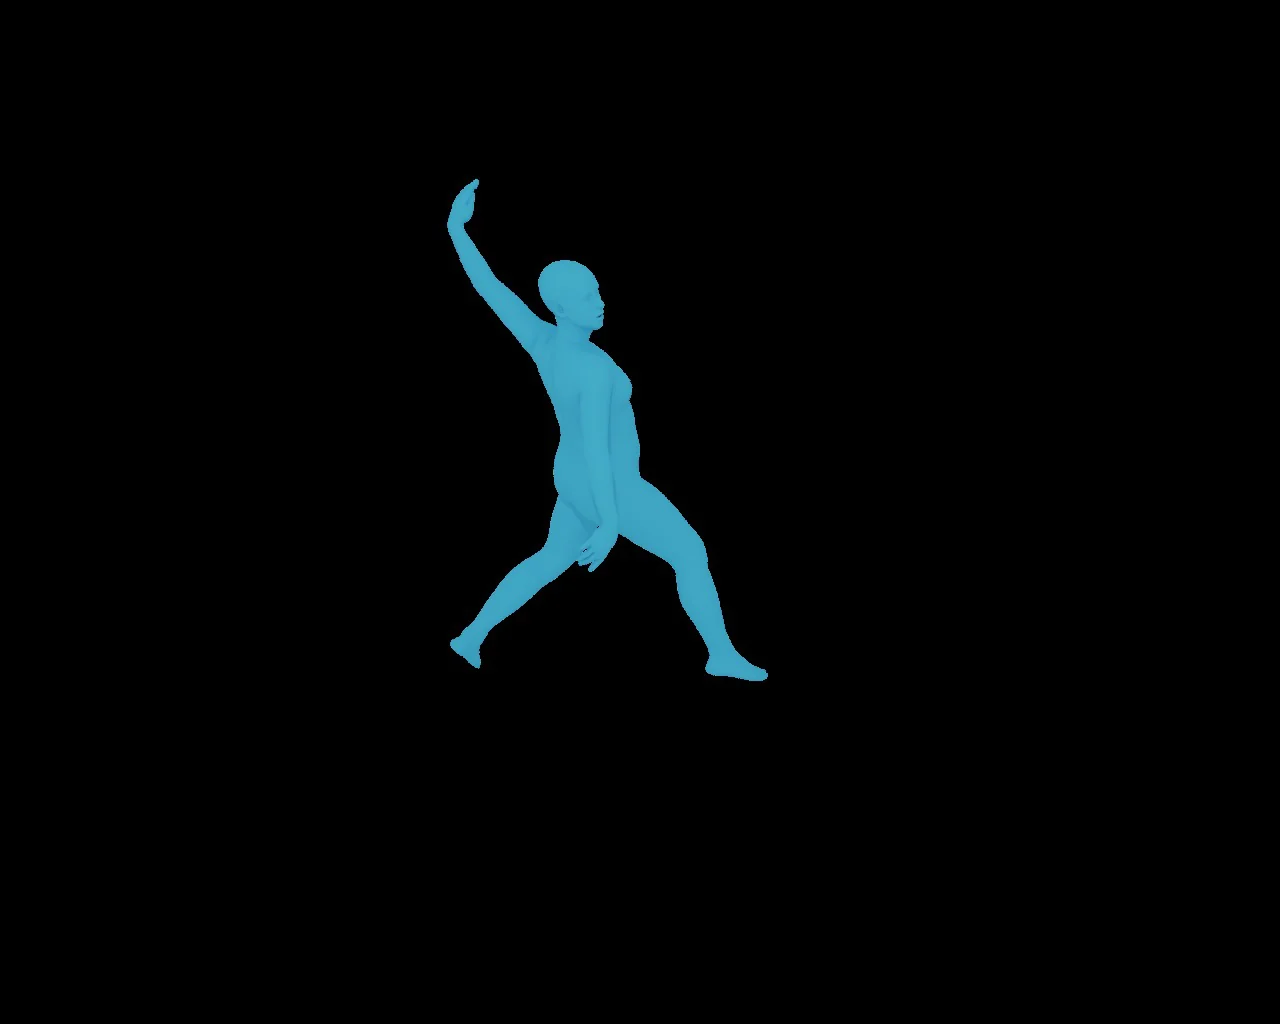
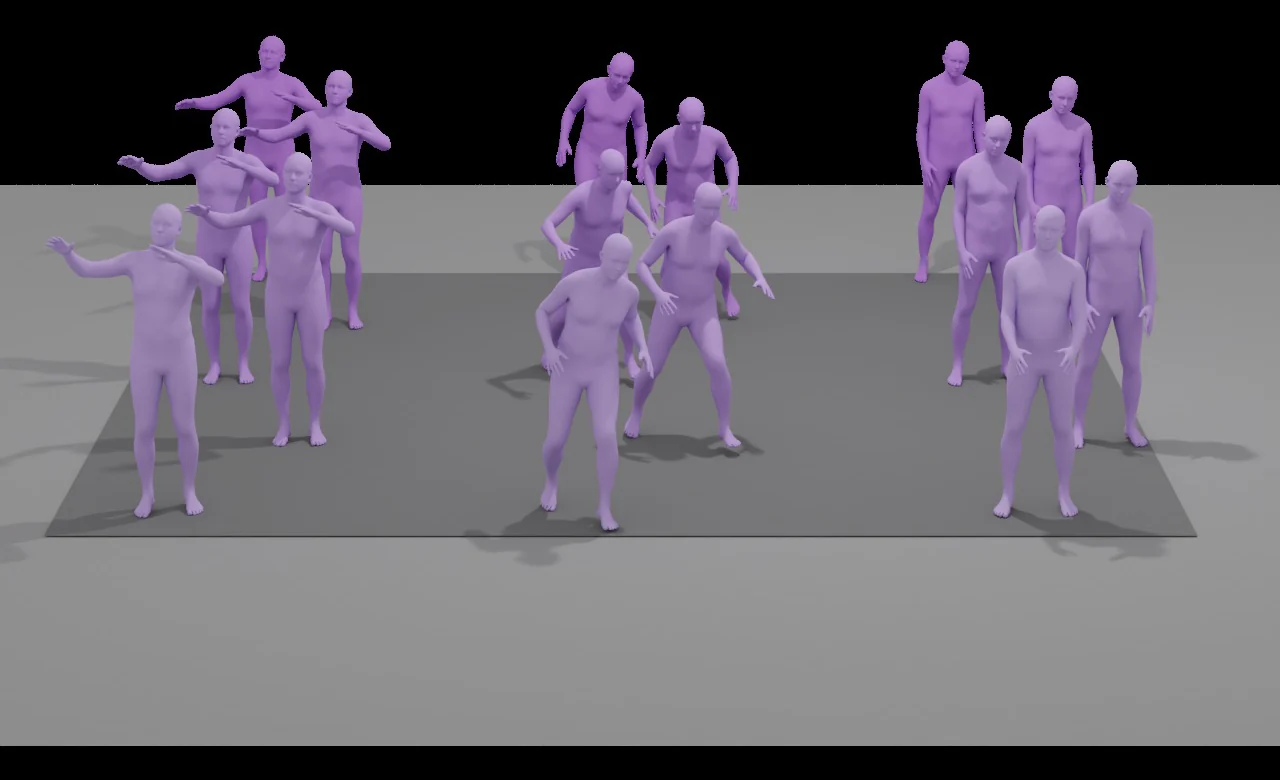
Motion-X paper figure

Motion-X: A Large-scale 3D Expressive Whole-body Human Motion Dataset

15.6M frame-level whole-body pose annotations across 81.1K motion sequences, plus a fully automatic video-to-motion-and-text pipeline that moves capture out of the lab and into the wild.

Motion-X++Preprint · 2025
Motion-X++ paper figure

Motion-X++: A Large-Scale Multimodal 3D Whole-body Human Motion Dataset

Scaled further: 19.5M pose annotations and 120.5K sequences, with the first inclusion of 80.8K RGB videos and 45.3K audio clips — enabling audio-driven motion generation.

HumanMMCVPR 2025
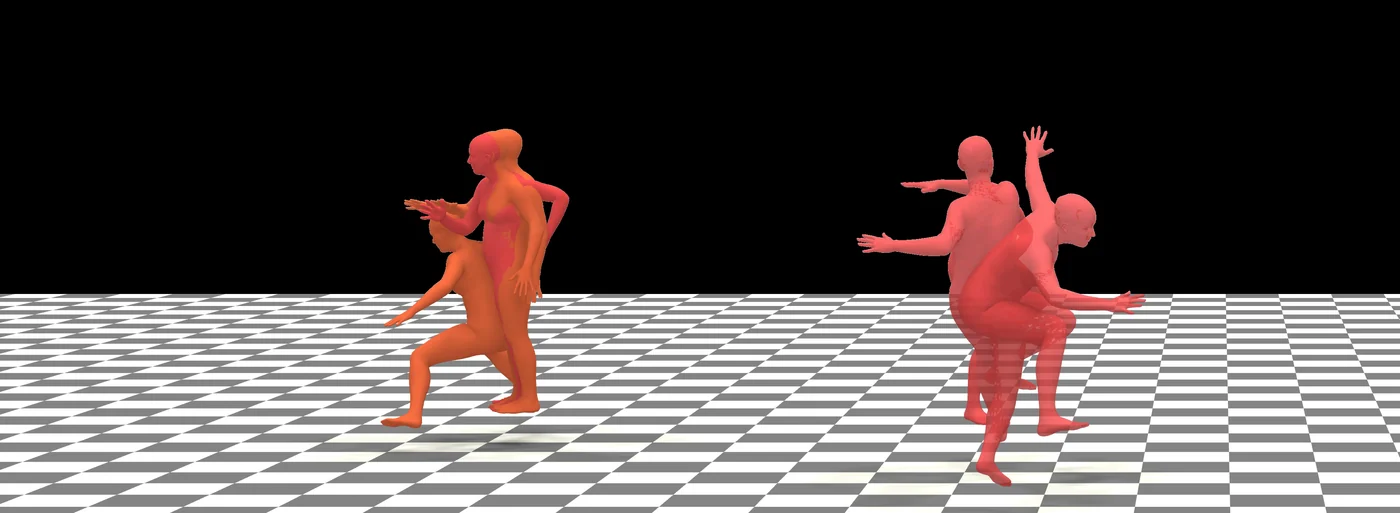
HumanMM paper figure

HumanMM: Global Human Motion Recovery from Multi-shot Videos

Recovering world-coordinate continuous motion from multi-shot in-the-wild videos: shot-transition detection, cross-shot alignment and an anti-foot-sliding integrator — so edited footage still yields long-sequence motion data.

MOTION RECOVERYarXiv:2503.07597 ↗

02Embodied Perception and Generalizable Manipulation

02 PAPERS
CODERSPreprint · 2024
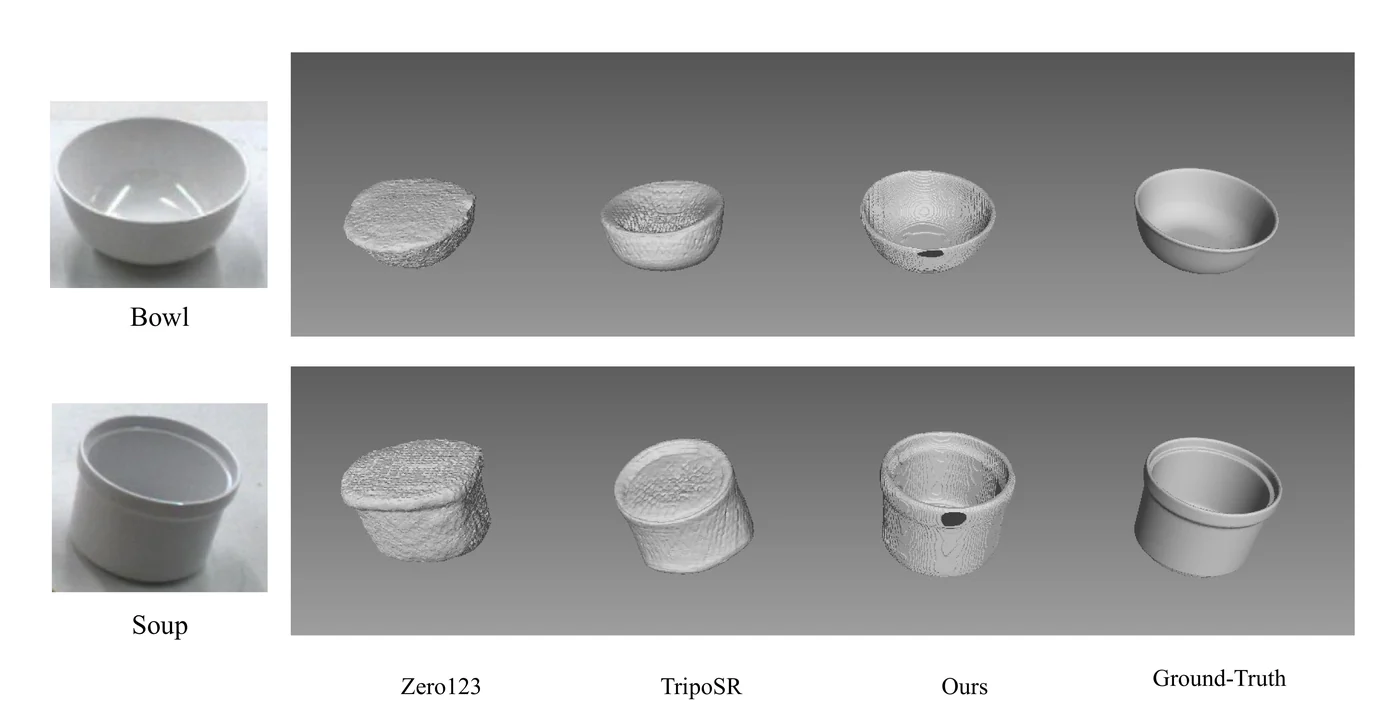
CODERS paper figure

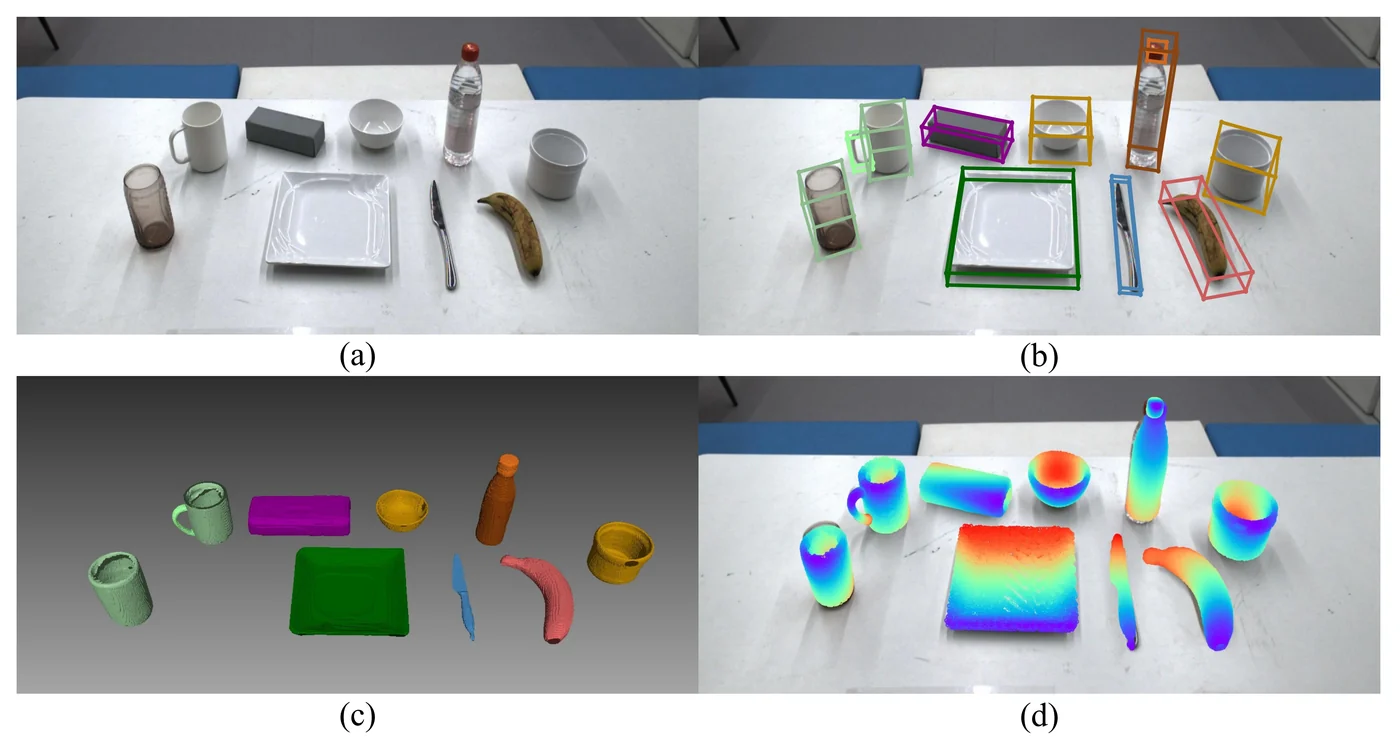
Category-level Object Detection, Pose Estimation and Reconstruction from Stereo Images

One-stage category-level detection, pose estimation and 3D reconstruction from stereo images, including transparent and specular materials; state-of-the-art on the public TOD dataset with simulation-to-real transfer to robot grasping.

M²-VLAIROS 2026
M²-VLA paper figure

M²-VLA: Boosting Vision-Language Models for Generalizable Manipulation via Layer Mixture and Meta-Skills

No end-to-end fine-tuning: freeze the VLM’s general perception, extract task-critical features via a Mixture of Layers (MoL), and let a Meta-Skill Module carry trajectory learning — zero-shot generalization with manipulation accuracy.

03Data Engine and Cross-Embodiment Skill Transfer

01 PAPER
RoboWheelPreprint · 2025
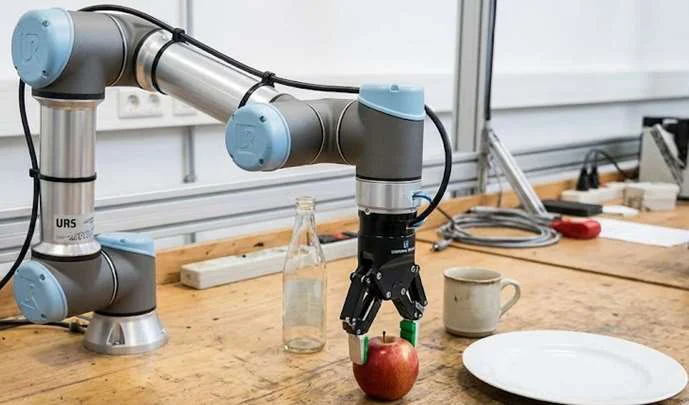
RoboWheel paper figure

RoboWheel: A Data Engine from Real-World Human Demonstrations for Cross-Embodiment Robotic Learning

HOI videos → high-precision reconstruction → RL-based physical refinement → cross-embodiment retargeting → Isaac Sim domain randomization; the first quantitative evidence that HOI can supervise robotic learning, on par with teleoperation.

CERT / 04 · CREDENTIALSVERIFIED — 05 ITEMS
20+Years of Brain-Inspired Science
3Years of AGI Market Exploration
NVIDIAInception Member
107Top-tier Publications
Million-hourreal-world operation dataset (UNIData)

Open for Research Collaboration

Joint research, data co-building and engineering deployment — open to researchers and industry partners.

SYS / ACTIONREV 2026.08